← All workPrettyFly OS · Internal Operating System
We run our own company on PrettyFly OS.
PrettyFly needed a way to see agent state, cost, failure, and handoff without chasing logs across servers.
- Monthly Operating Cost
- $50
- Client
- PrettyFly OS
- Industry
- Internal Operating System
- Engagement
- Ongoing
The screen
What was breaking
The work was distributed, but the operating state was not.
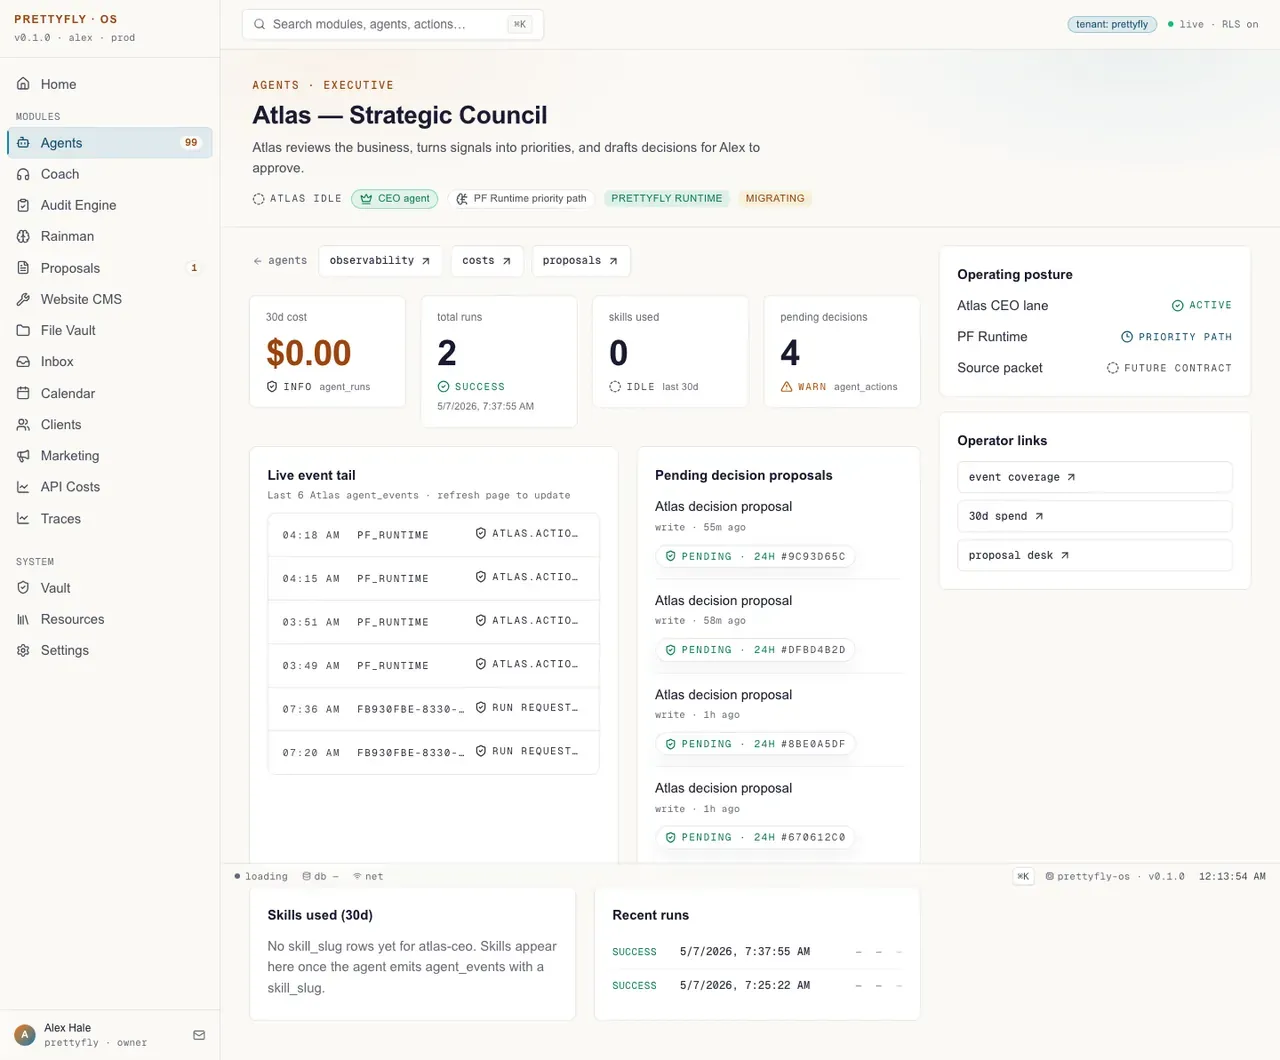
Agents were running across servers, but their health, cost, tasks and handoffs were scattered through logs and local state. We could not trust more of our work to them until we could see all of it in one place.
- Agent health lived outside a shared operating view.
- Failures could hide until someone checked the wrong place.
- Cost controls were separate from the work being done.
- Task handoffs had nowhere shared to live.
What runs now
A PrettyFly OS route for agent work: observe, budget, trip, trace, hand off.
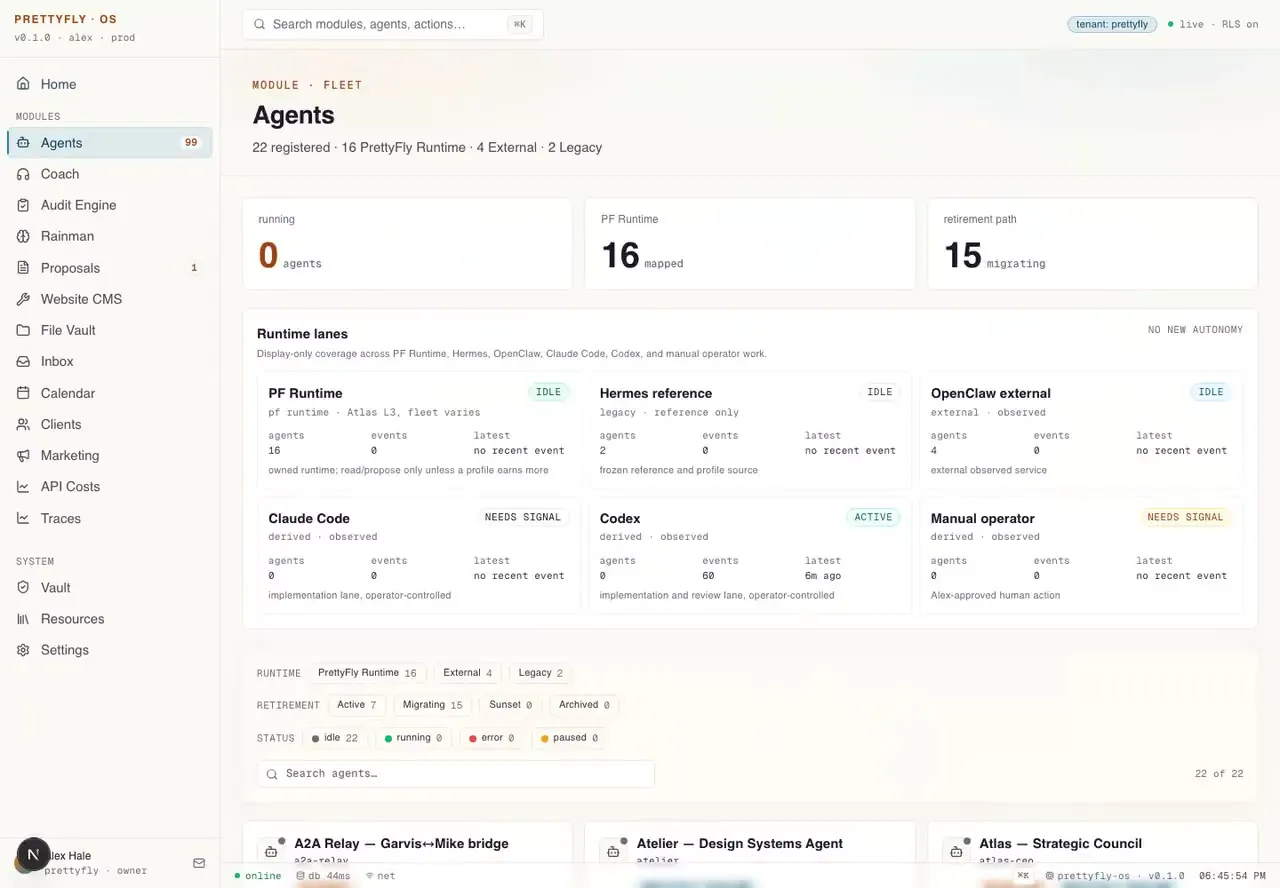
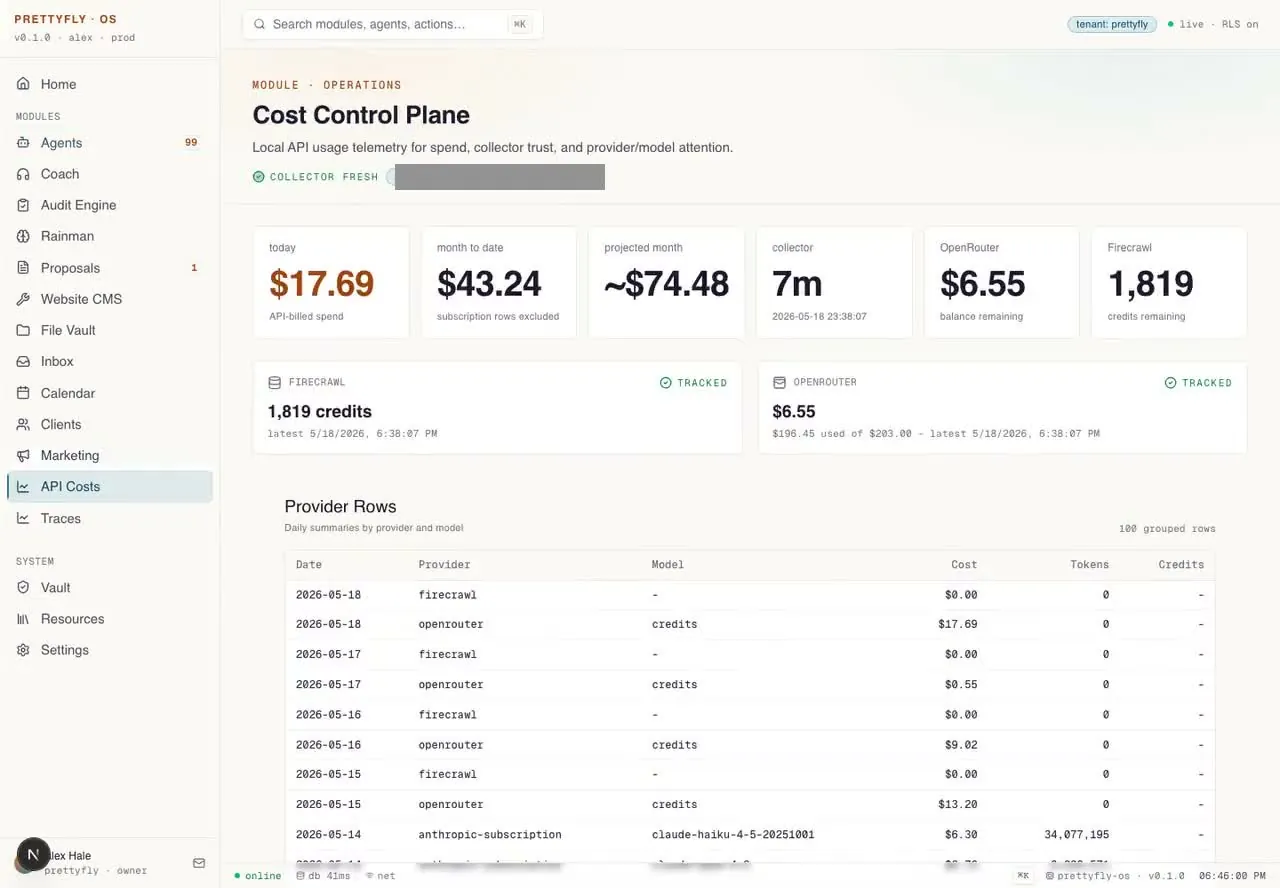
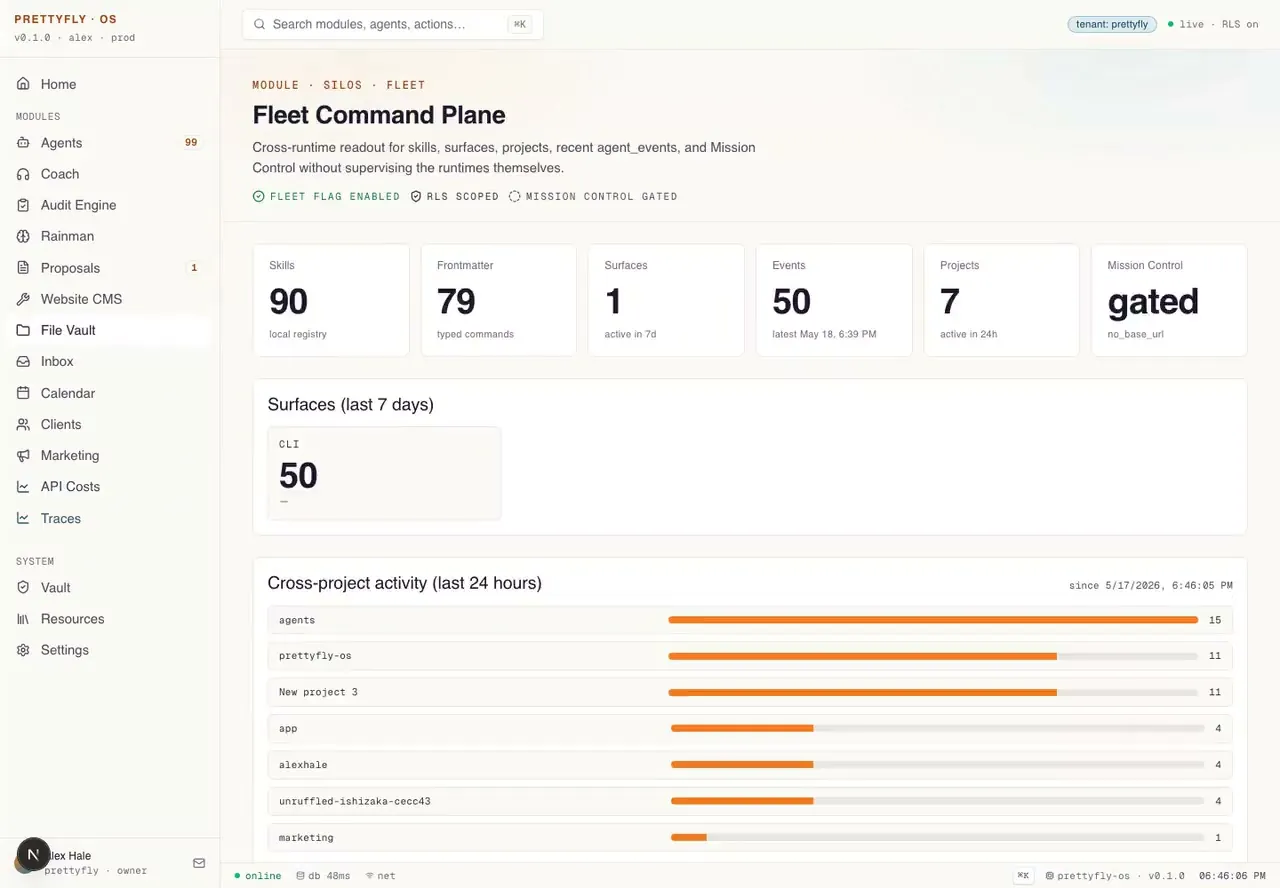
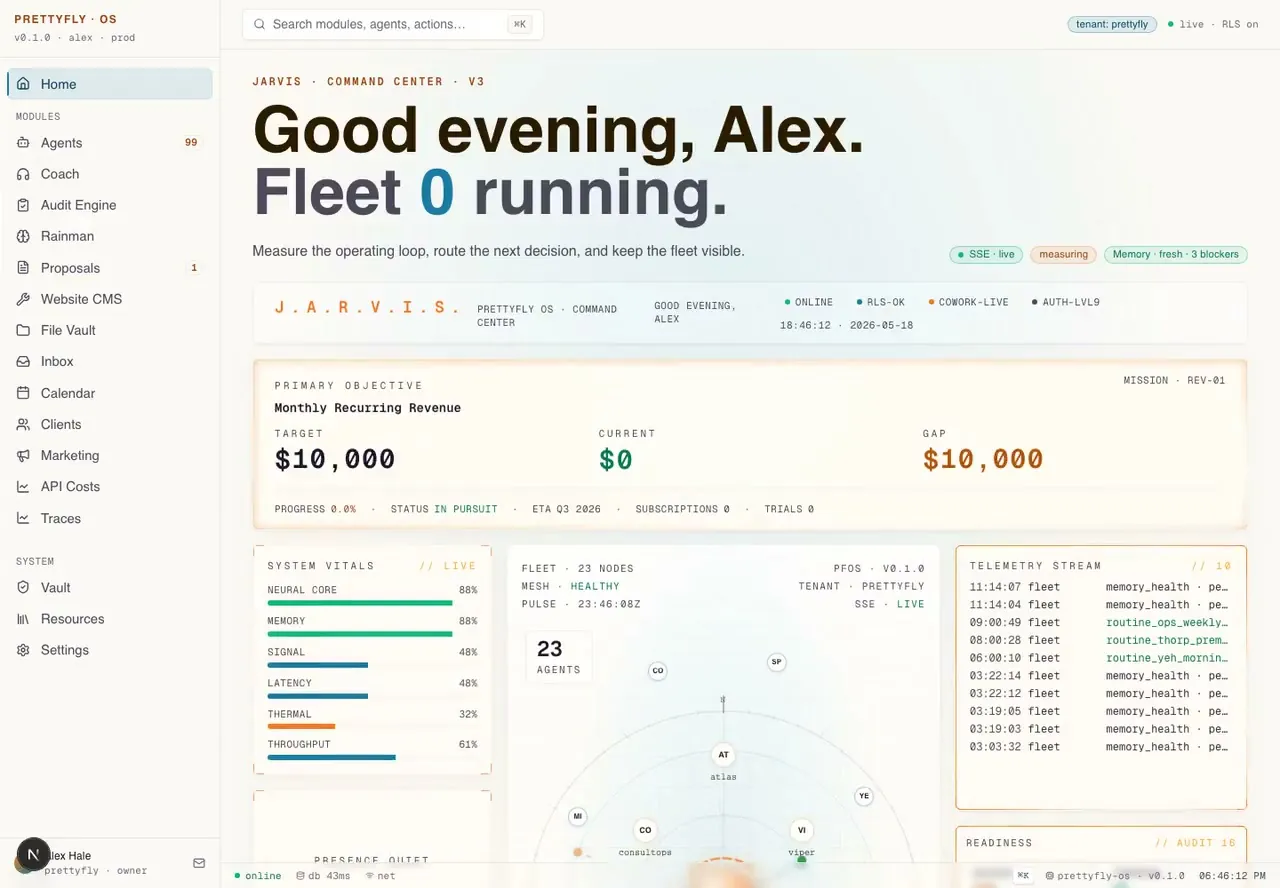
We built one screen for the fleet: live state, real-time events, circuit breakers, spend against budget, tracing, and tools our own development sessions can call.
What we built
Fleet state
Seven agents report into a shared view with real-time event streaming.
Circuit breakers
Repeated faults trip the route and make recovery explicit.
Cost readout
Per-agent spend, daily budgets, tracing, and monthly reports sit beside the work state.
18 MCP Tools
Observability and task tools are exposed directly to development sessions.
Small runtime
A raw Node.js HTTP server keeps the coordination layer inspectable.
Two auth modes
Supabase JWT handles dashboard access; bearer tokens handle machine communication.
What shipped
Live, and how we find our own problems first.
- Agents Running 24/7
- 7
- Monthly Cost
- $50
- MCP Tools
- 18
- NPM Dependencies
- 0
Built with
Every one of these started the same way.
A free twenty-minute call.
Tell us how calls, quotes, and invoicing work today, and we'll tell you where we think the money is going. No pitch, no deck.